Engineers Are Headless No More: How Data, Knowledge, and AI Empower Teams to Lead
Engineers see the future – but too often, management says “No, thank you.” In 2026, the balance of power shifts. By justifying actions with hard data (using operational telemetry to spot inefficiencies like failing to enable free cooling when outdoor air is cool and dry), turning knowledge into a strategic asset (capturing decision context and automating learning from daily work), and putting AI to work with clear, repeatable actions (predictive alerts, lightweight digital twins, and intelligent triage), engineers can lead with evidence, not hunches. The goal is to stop feeling headless and start building systems that actually work.
Higher Density Isn't Always Better!
Chasing higher rack density isn't always the smart move. The Uptime Institute 2026 survey reveals that pushing beyond 20–25 kW per rack delivers diminishing capital cost savings - the specialised power and cooling gear required at extreme densities actually commands a cost premium.
Gas Turbine vs. Diesel Generator for Australian Data Centres: A Technical Analysis
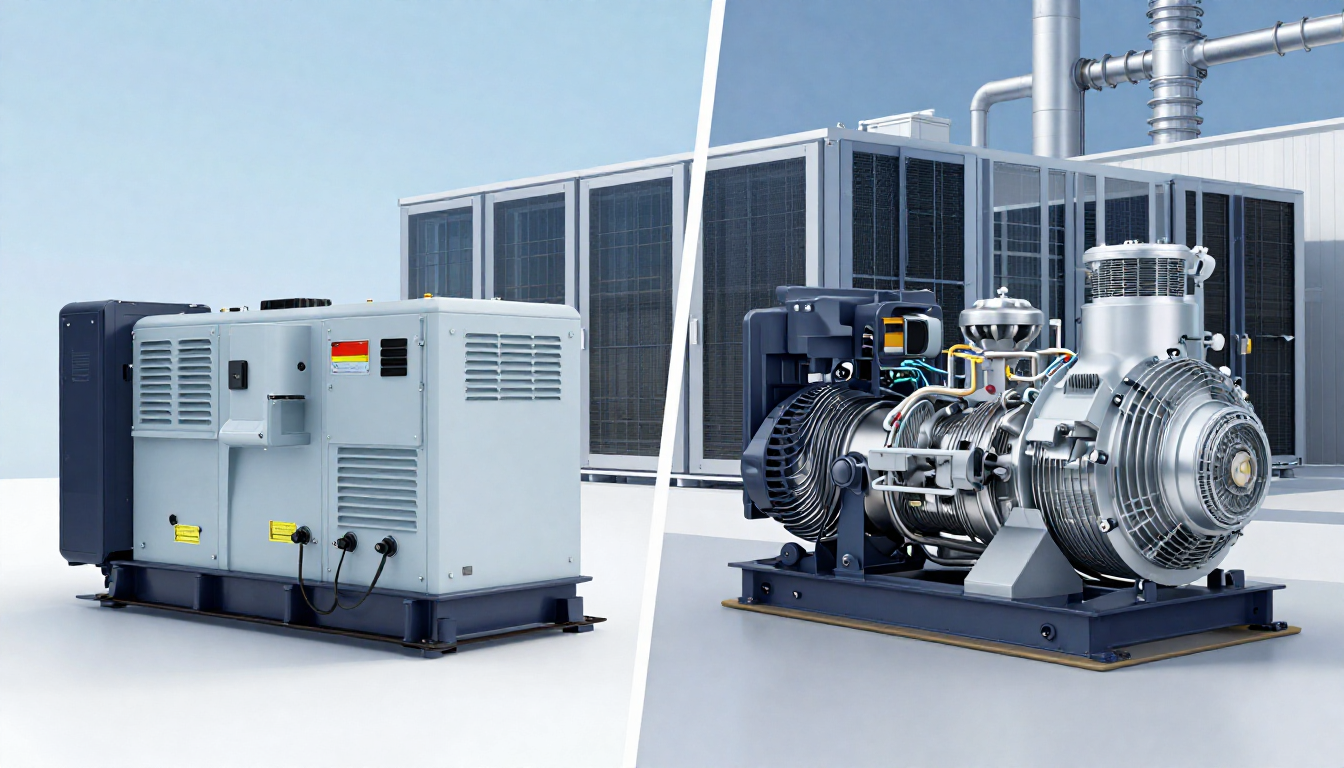
The choice between diesel generators and gas turbines for Australian data centres is a decision with significant financial and operational consequences. Diesel delivers proven reliability, rapid start-up, and a mature local service ecosystem at a lower initial cost. Gas turbines offer lower fuel costs, reduced emissions, and cooling integration but demand higher capital investment, longer lead times, and specialised maintenance capabilities. As AI workloads and sustainability targets reshape the industry, understanding this trade-off in technical depth has never been more critical.
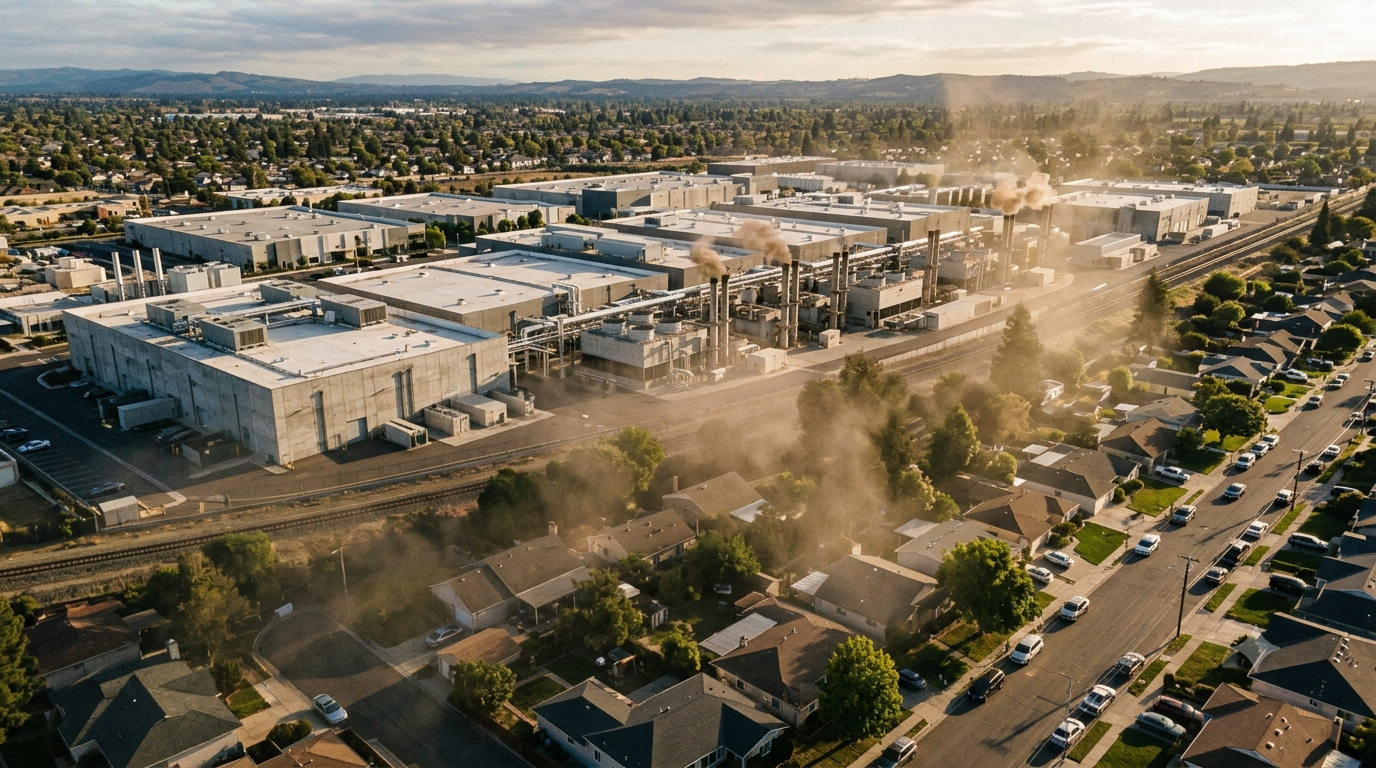
The Hidden Cost of Australia's AI Boom: Why Our Data Centres Are a Public Health Time Bomb
AI's rapid growth brings not only opportunities but also public health risks that are increasingly borne by individual communities, especially those with disadvantaged populations. From the siting of data centres to the sourcing of electricity and the scheduling of AI workloads, the design choices made today will determine whether AI exacerbates or alleviates health burdens.
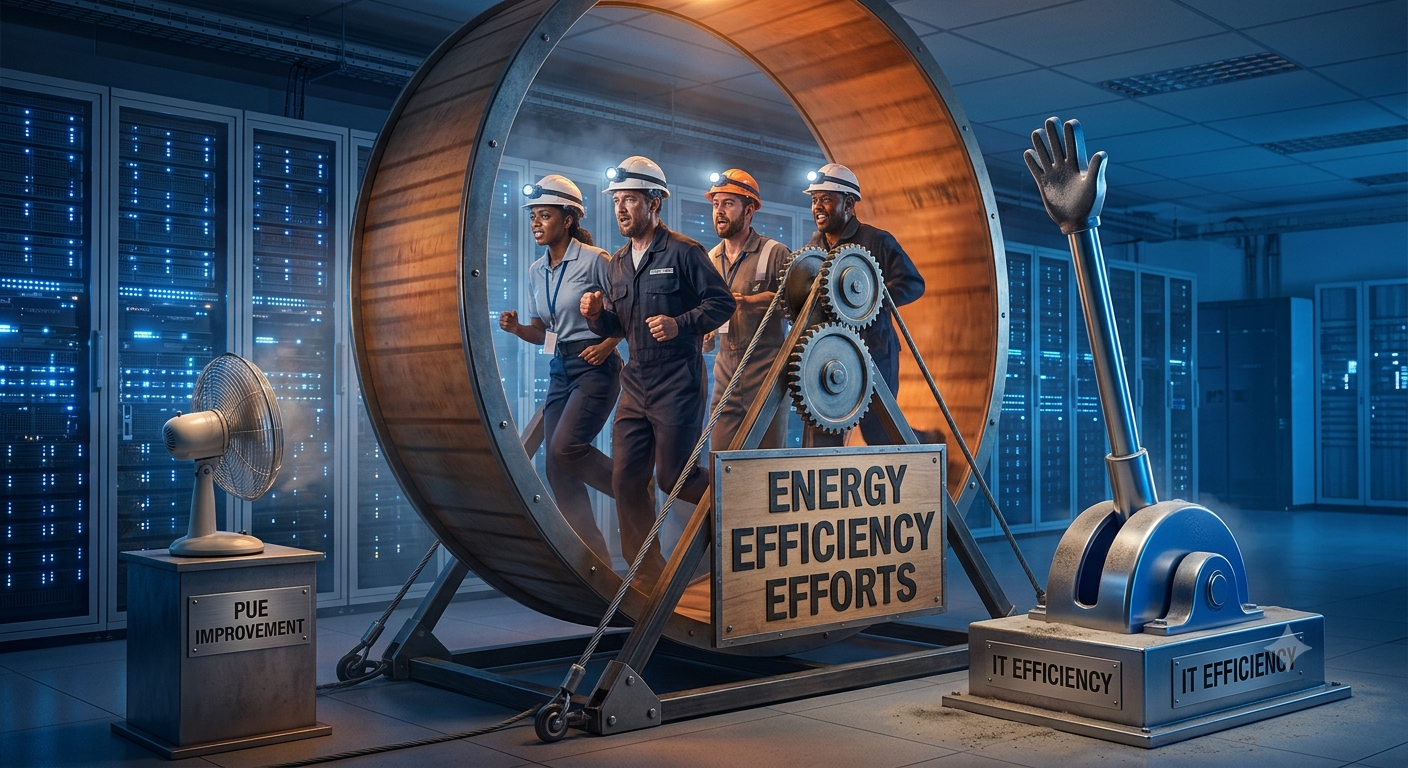
Why data centre energy efficiency is stuck - and how to fix it
Most data centre operators focus their efficiency efforts on the facility side - cooling systems, airflow management, power distribution - because that's where PUE lives and what regulators measure. But the facility side is no longer where the biggest gains are. As data centres become more efficient, IT equipment consumes the vast majority of energy, yet most sustainability programs still pour time and money into shaving fractions off PUE while ignoring the real energy hog: underutilised IT gear. Run your IT more efficiently, and you cut total energy consumption dramatically - far more than any facility-side tweak could ever deliver. And IT efficiency doesn't stop at energy savings; you also get less heat, lower cooling load, less floor space, and reduced water use. PUE improvements alone don't deliver any of these extras. The bottom line: if you're serious about cutting costs and emissions, you can't afford to treat IT efficiency as someone else's problem. The biggest lever is already sitting in your racks - it's time to pull it.
On-premise AI inference is on the rise. Can Australian enterprises make it work?
Australian enterprises want to run AI inference on-premise - but the infrastructure must deliver. According to Uptime Institute, the key is sustained hardware utilisation above 65%, yet most organisations fall short. Model choice, cooling demands, and data sovereignty add further complexity.
The good news? Smaller inference models can run in existing facilities with minimal upgrades. For those ready to scale, modular solutions - from compact edge units to full-scale prefabricated data centres - offer a clear path forward, including locally manufactured options with flexible equipment choices and comprehensive service support.
On-premise AI isn't just possible - it's a strategic advantage.
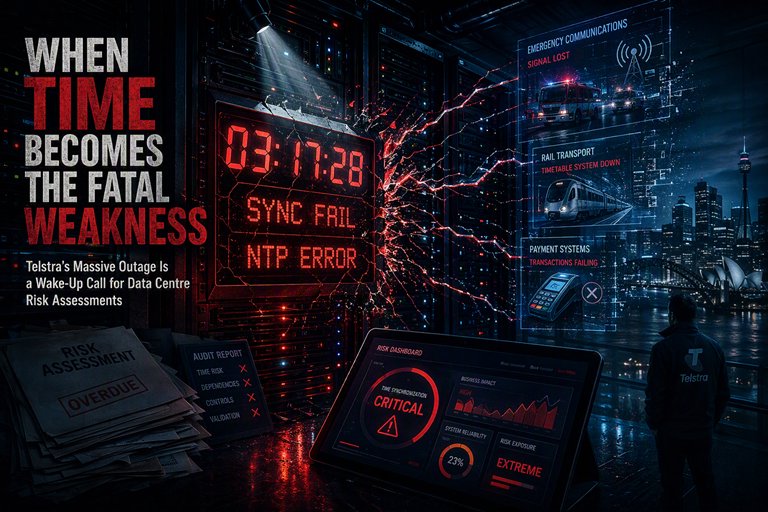
When Time Becomes the Fatal Weakness: Telstra’s Massive Outage Is a Wake‑Up Call for Data Centre Risk Assessments
When Telstra’s mobile network collapsed at 4:30 AM on 8 July, it wasn’t just a telecoms glitch. Over 600 Triple Zero calls failed. Trains stopped. Payments froze. The culprit? A software defect that broke clock synchronisation – a vulnerability that Australian experts had warned about for years.
That same week, Uptime Institute revealed that only 39% of data centre operators assess third‑party systemic risks – and the share conducting any resilience risk assessments has fallen from 89% to 81% in just two years. Telstra is a brutal reminder: the risk assessment you skip today is the emergency call that fails tomorrow.
The New Rules of Generator Reliability
Part 2: The Economics of Smarter Testing - Global Fuel Costs, HVO, and the 60-Second Solution
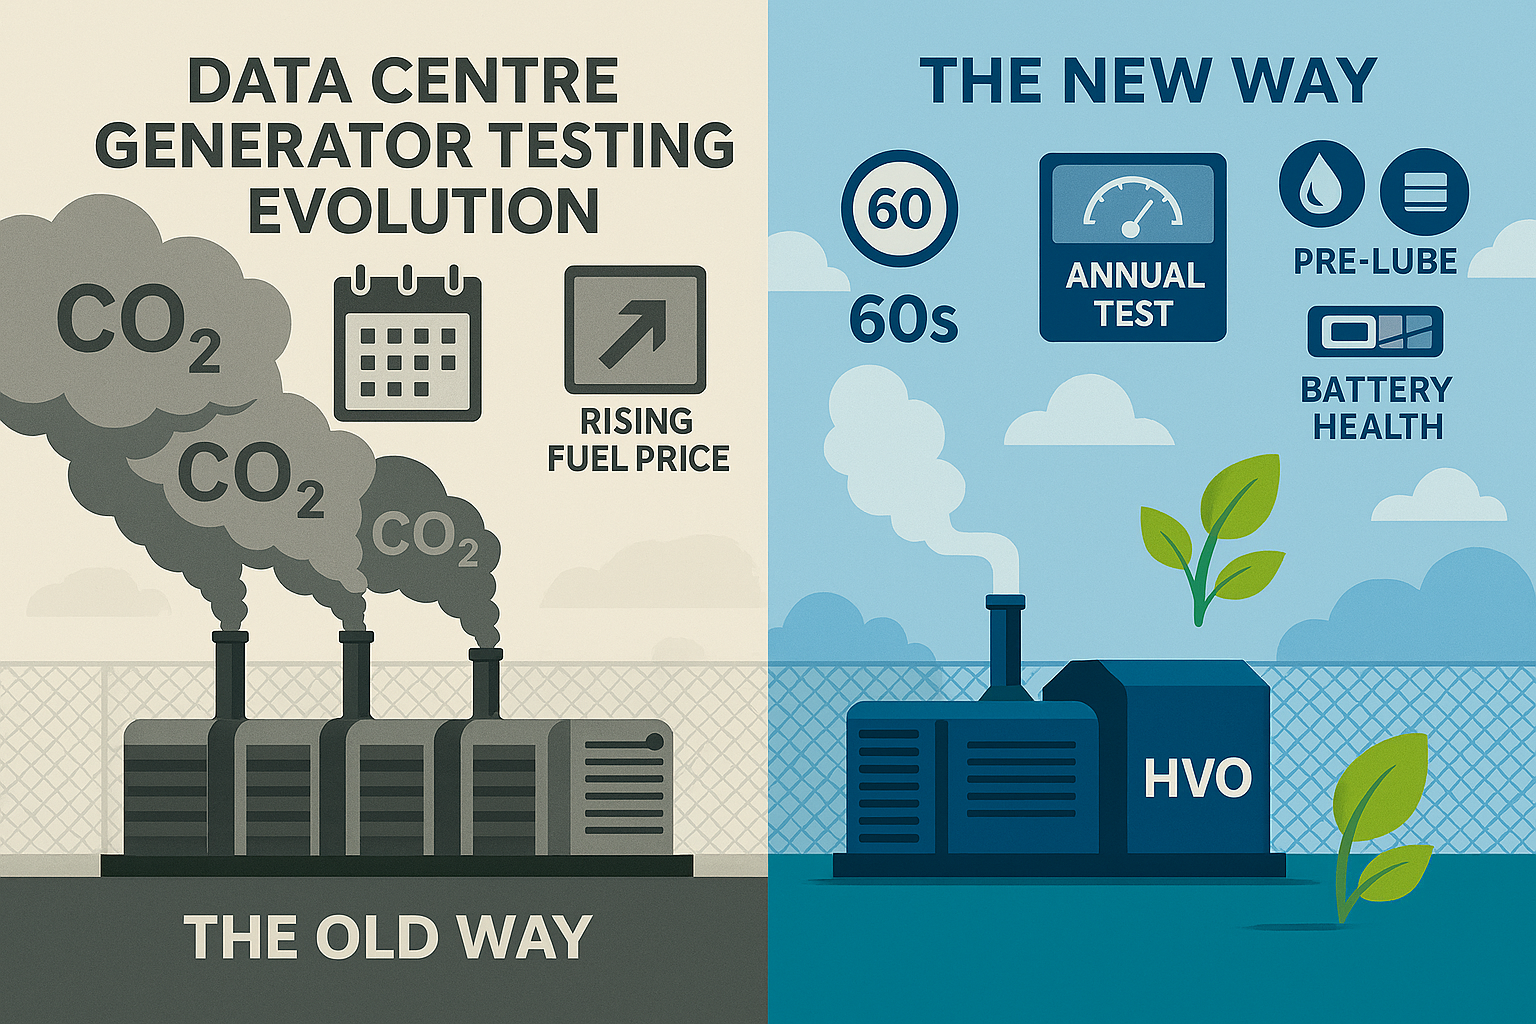
With Australian high diesel price, a 500 MW campus spends over $2 million annually on testing fuel alone. The solution? Cut low-load tests from 15 minutes to just 60 seconds – the same reliability, but savings in million and CO₂ emission reduction each year. For those going further, HVO offers up to 90% lower lifecycle emissions and 10-year storage stability. The monthly test ritual is over. Smarter, sustainable reliability has begun.
The New Rules of Generator Reliability
Part 1: The AI Paradox - Why Traditional Testing Is Failing Data Centres
The Uptime Institute defines on-site generation as the primary source of power for Tier data centres - the grid is merely an "economic alternative." This has driven monthly generator testing for decades. But here's the catch: frequent short, low-load runs often do more harm than good. They clog Diesel Particulate Filters (risking failure during real outages) and fail to activate SCR systems. Meanwhile, AI campuses now require 230 MW of diesel capacity, with supply chains stretched into 2028. Smarter testing is no longer optional – it's a necessity.
Data centre investment boom: record cheques, but can we build – and run – them?
Australia's data centre gold rush is well underway, with Amazon, Microsoft, and Anthropic committing tens of billions to new facilities. But the real challenge isn't signing the cheques - it's securing the grid capacity, water for cooling, and the skilled operators needed to keep these complex facilities running for the next two decades.
Value is not extracted from a data centre by its architecture; it is extracted by its operations. Without a world-class operations team, even the most impressive facility is just an expensive, inert building. Building is the easy part. Running it for the next twenty years is where the real battle begins.
Your AI Strategy Is Now a Grid Strategy (And a Water Strategy)
The next bottleneck in AI isn't a smarter model - it's electricity and water. With Australia's data centre capacity set to more than quintuple by 2035, the grid is straining and the taps are running dry. Your AI strategy just became your energy and water strategy.
It’s not your UPS. It’s not your generator. So why is your data centre still going dark?
Uptime's 2026 outage analysis delivers a clear warning: after years of steady gains, reliability improvements are stalling. Power remains the leading cause of impactful outages, but the biggest emerging threats now sit outside the fence line - fibre cuts, grid constraints, and third‑party failures are all on the rise. Human error is a factor in the vast majority of incidents, and most outages could have been prevented with better processes. Costs keep climbing, with a growing share of outages now reaching seven figures. Meanwhile, confidence in public cloud resiliency is falling, and AI workloads are introducing new, poorly understood risks. If your resilience strategy still focuses only on internal systems, you're already behind.
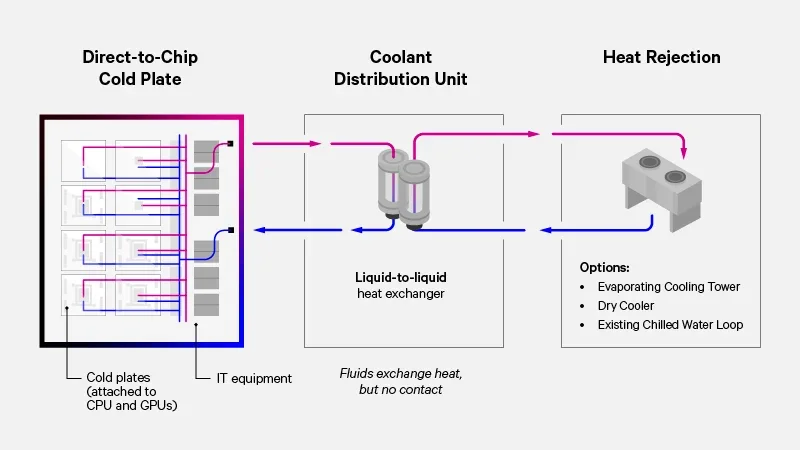
Beyond the Plumbing: Engineering Direct-to-Chip Cooling for AI Workloads
The Hidden Engineering Challenge of Direct‑to‑Chip Cooling
AI workloads don’t just run hotter – they run differently. Training a large language model can ramp GPU utilisation from 60% to 100% and back down within milliseconds, pushing coolant temperatures above 45°C in closed loops. That rapid thermal cycling demands response times measured in seconds, not minutes.
Direct‑to‑Chip (D2C) liquid cooling is the industry’s answer, but it introduces new risks: fluid inches from $40,000 GPUs, hundreds of potential leak points, and coolant chemistry that can corrode piping from the inside out.
And if a cooling anomaly strikes? You have roughly 5–10 seconds before the silicon throttles – or crashes a multi‑day training job.
Traditional data centre operations weren't built for this. Managing D2C requires fluid chemistry expertise, concurrent maintenance procedures for live liquid loops, and unified IT‑facilities alarm chains.
That’s the new engineering reality of AI infrastructure.
From Static Inventory to Lifecycle Intelligence
In a recent post, Uptime Institute highlighted that critical spares management is no longer a static decision - it's a moving target. Operators are shifting toward hybrid strategies that blend on-site stock with vendor agreements, but the real gap is lifecycle intelligence: knowing where each asset stands in its service life so spares, maintenance, and replacement plans evolve accordingly.
From Air to Liquid Fire: Building the AI Factory - Why Old-School Data Centres Just Lost Their Cool
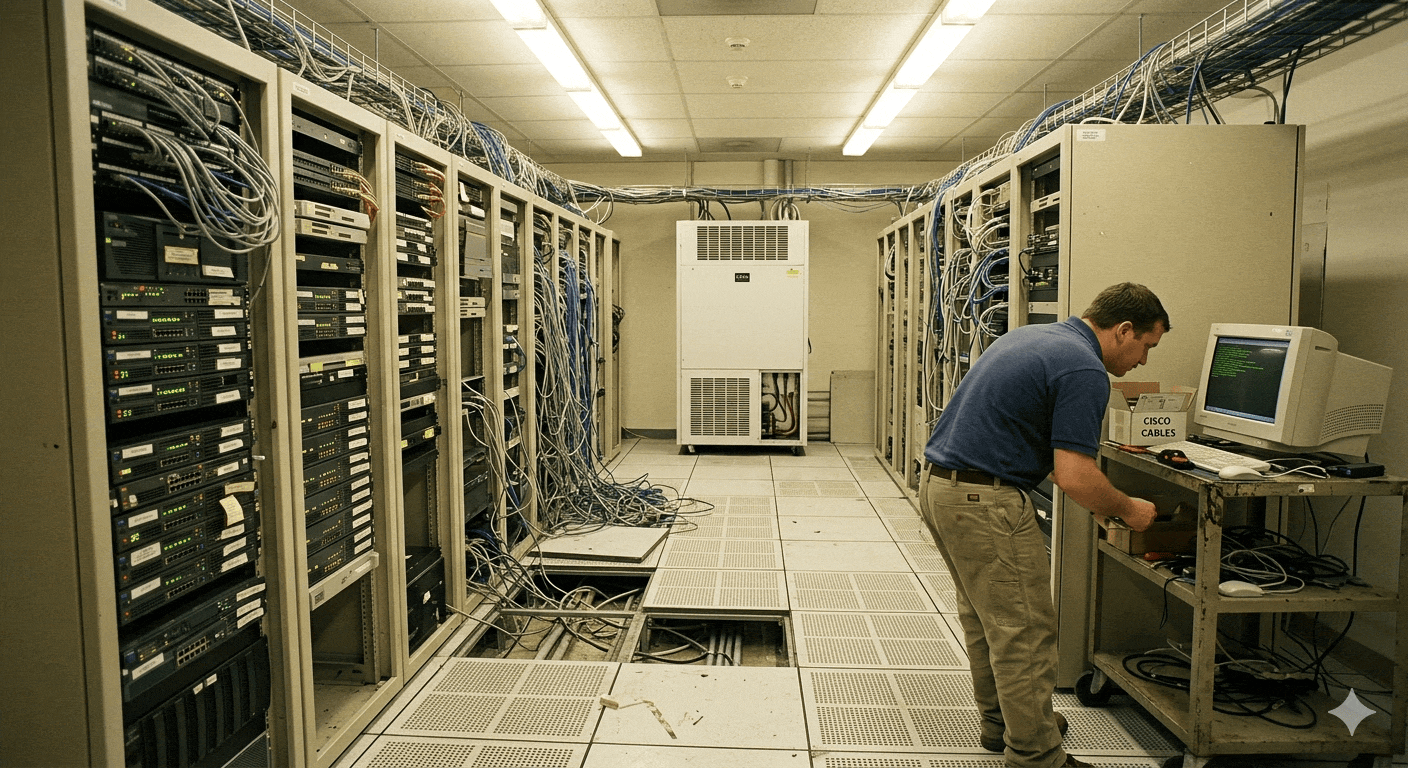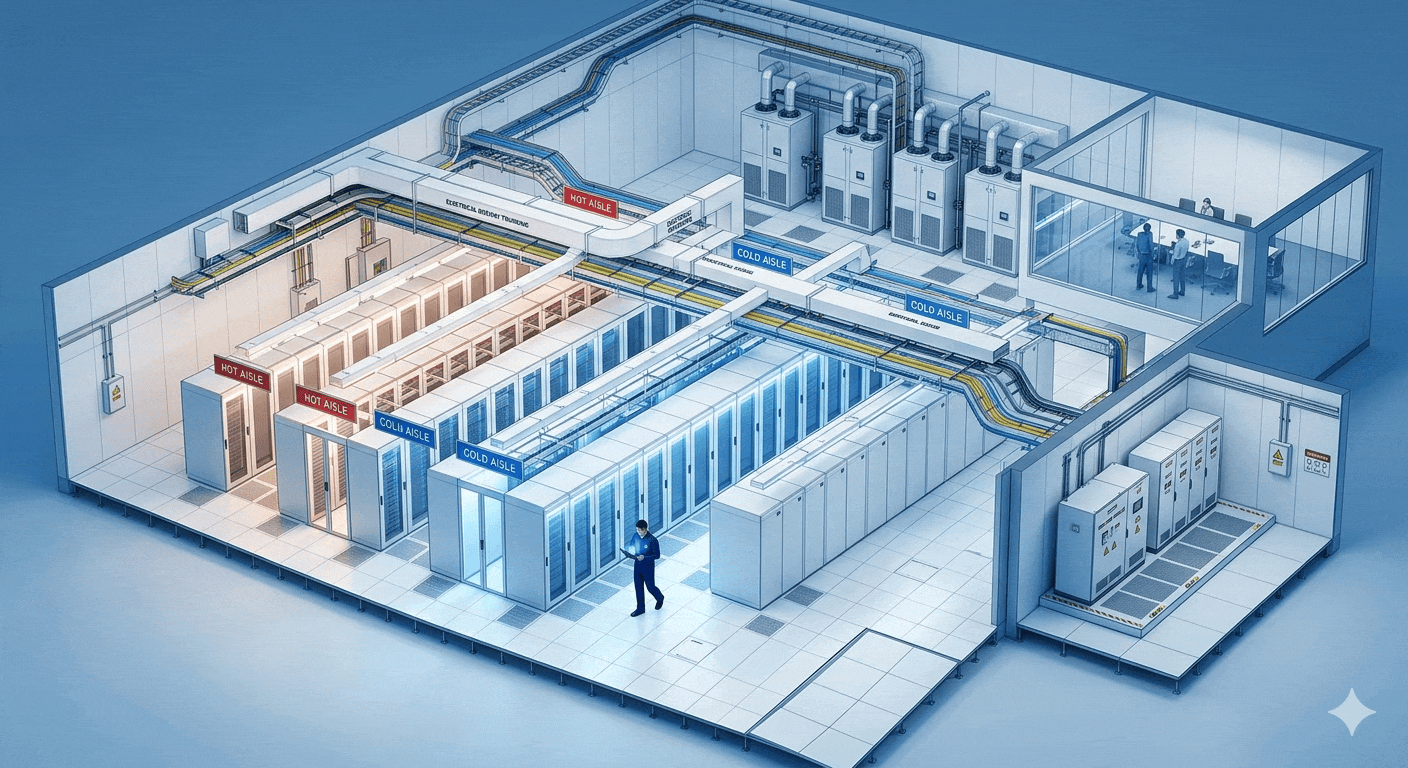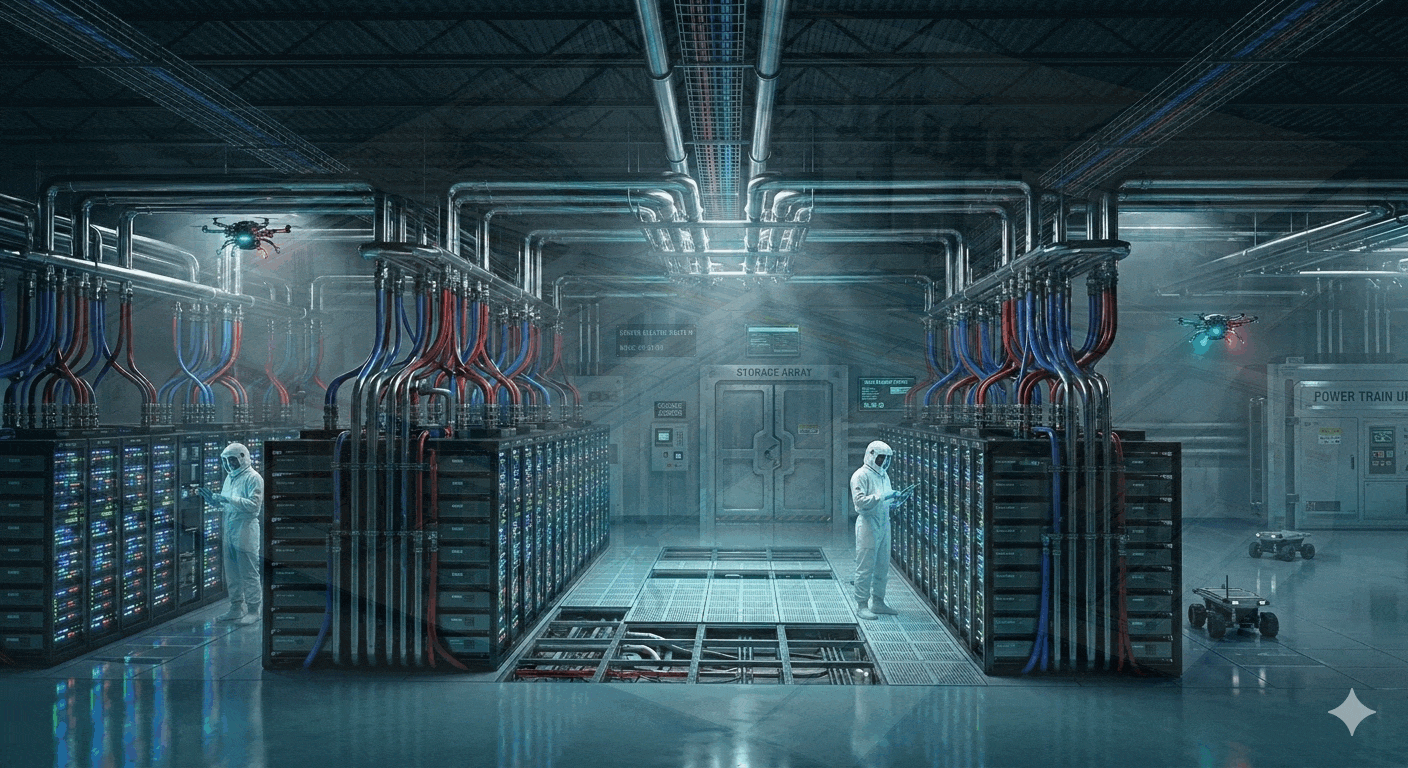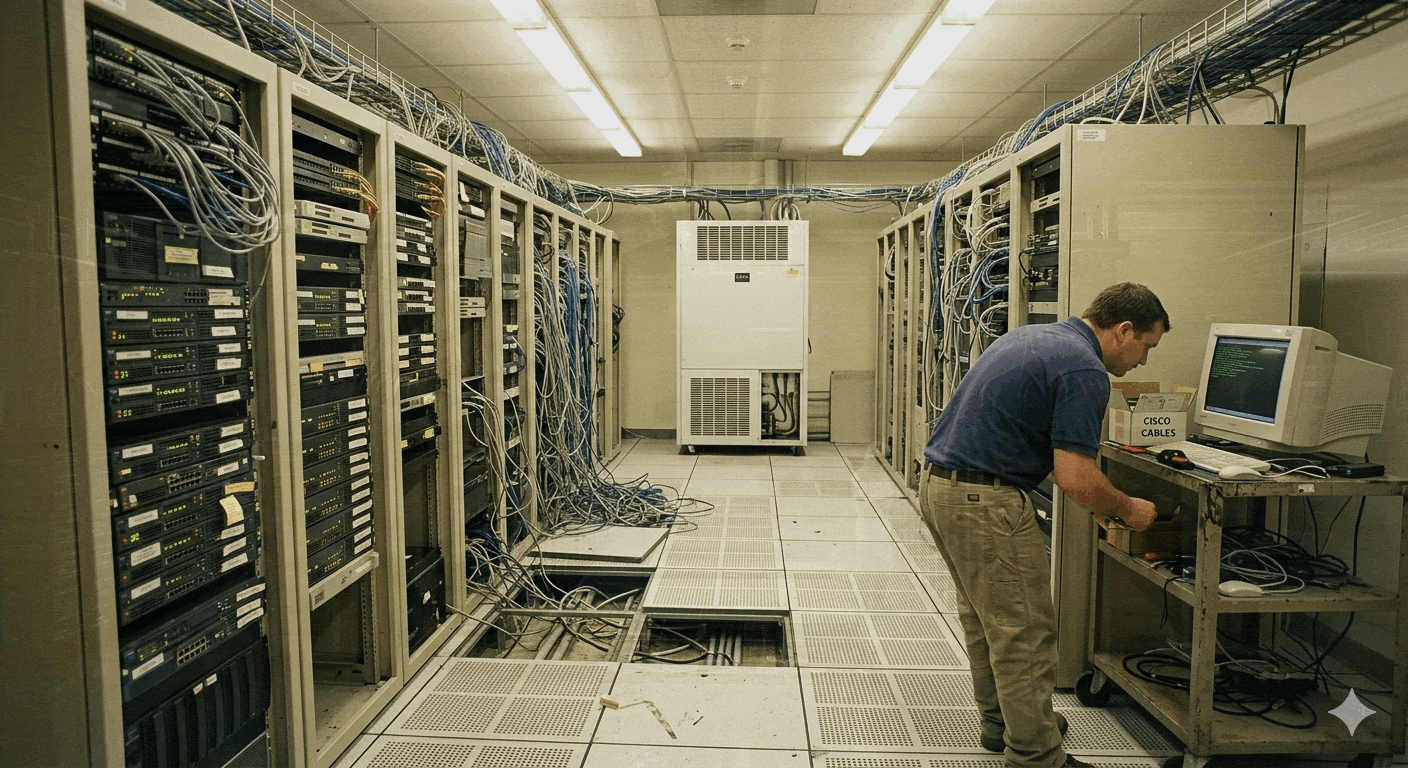
Building an AI factory is nothing like a traditional cloud data centre. Cloud racks run at 10-20kW; AI racks scream past 120kW. That changes everything - power, cooling, and especially the build process.
Forget stick-built construction. AI factories demand prefabricated Power Train Units (PTUs) - factory-assembled electrical vaults craned into place and operational in days, not months. Liquid cooling replaces air, forcing vendor lock-in and component-level compatibility testing.
On certification: pursue Tier III for concurrent maintainability (service without shutdown), but accept N+1 cooling rather than 2N fault tolerance. Pure Tier IV doubles your piping and leak points for marginal gain.
Post-build, operations shift from IT to industrial engineering. Methods of Procedure (MOPs) govern every valve turn. Programmed maintenance runs every 2-3 weeks. Your technicians now need fluid dynamics literacy.
The verdict? The cloud was built on air. The AI factory runs on liquid, modular steel, and surgical precision. Build accordingly.
The Uptime Institute 2026 Vendor Survey: 3 Hard Truths About Data Centre Outages
The Uptime Institute's 2026 Vendor Survey reveals three hard truths: AI is mostly used for monitoring (54%) and predictive maintenance (44%) - not fixing problems. Cost savings (56%) and energy efficiency (55%) are the top metrics, not uptime. And human error (30%) and power failures (25%) still cause most outages.
Outage frequency may be declining, but the cost of each outage is rising - one in five now exceed $1 million.
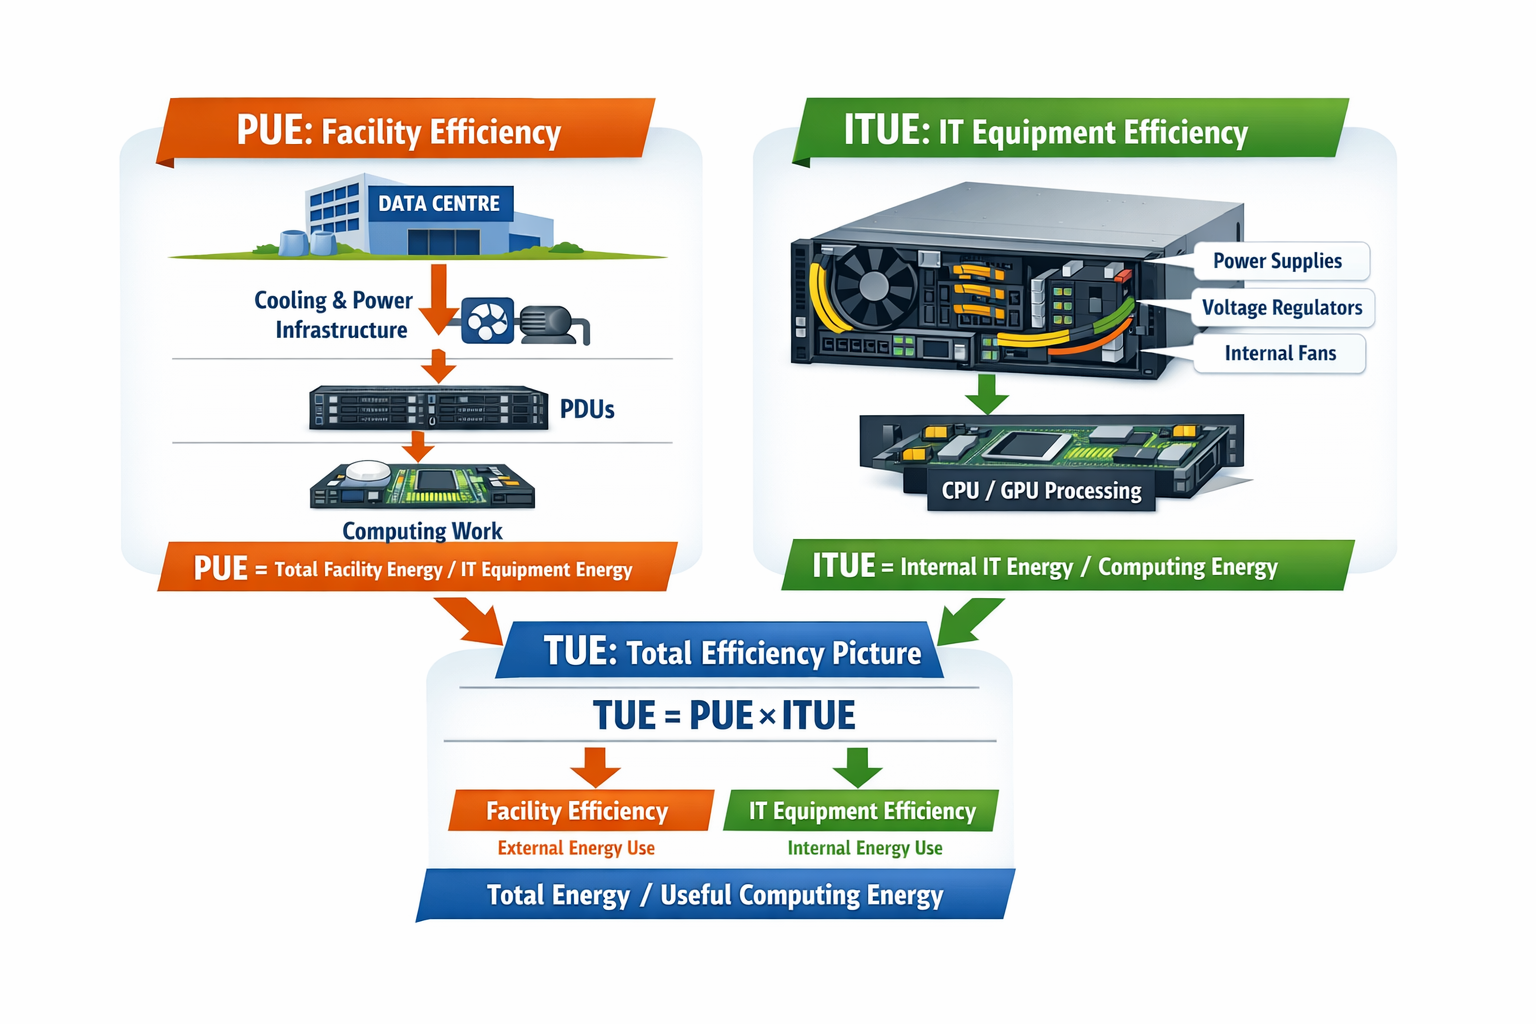
Beyond PUE: Why Total Power Usage Effectiveness (TUE) Is the Metric Liquid Cooling Has Been Waiting For
PUE has been the data centre efficiency standard for years, but it was never designed for liquid cooling. Total Power Usage Effectiveness (TUE) goes deeper - capturing losses not just at the facility level, but inside the servers themselves. With the Uptime Institute’s 2025 survey showing a stagnant average PUE of 1.54, it’s time for a better metric. This article explains what a good TUE looks like, how it compares to PUE, and why liquid‑cooled data centres need TUE to measure what truly matters.
Why Operations Can’t Be an Afterthought: The 20-Year Lesson from 2014
The 20‑Year Payoff: Why Operations Must Lead from Day One
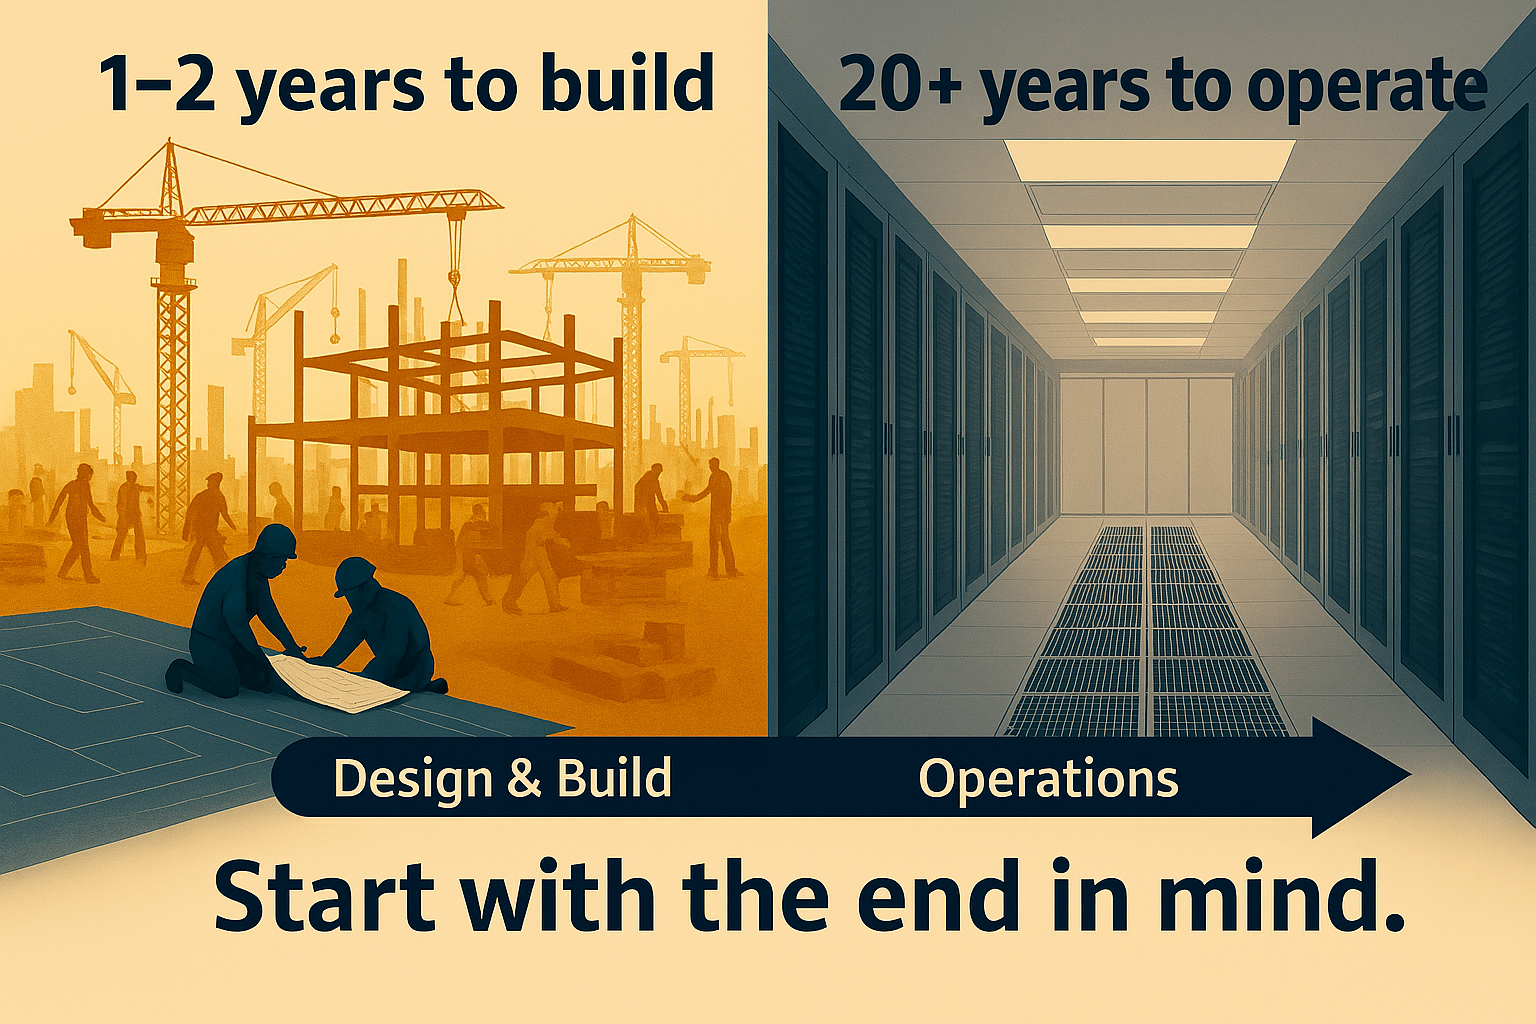
A 2014 Uptime Institute article, “Best Practice Is to Start With the End in Mind,” made a deceptively simple argument: involve data centre operations at the very beginning of any capital project. More than a decade later, that advice is more urgent than ever.
Why? Because a data centre’s design and construction typically take 1‑2 years, but its operational life spans 20+ years. Yet operations is still often treated as an afterthought—brought in only after commissioning, when the biggest opportunities to shape maintainability, efficiency, and total cost of ownership have already passed.
As the article’s author, Lee Kirby, noted: if value engineering happens without operations input, “increased costs over the life of the data center may dwarf any initial savings.” In other words, value is extracted from a data centre by operations, not by the original build.
The solution is to embed operations expertise from day one—and to equip teams with the right frameworks. Turn a decade‑old insight into a 20‑year advantage.
Beyond the Headlines: Why the Iran War Makes Operational Sustainability a Strategic Imperative
Energy Crisis & Operational Sustainability: Why the Iran War Changes the Game
Global energy markets are volatile, and the recent Iran‑related conflict has pushed price stability and supply security to the forefront for Australian critical infrastructure operators. In this environment, relying on carbon offsets alone is not enough—resilience starts with facility and IT efficiency.
As the Uptime Institute’s 2025 article The Two Sides of a Sustainability Strategy makes clear, operators must prioritise operational fundamentals: optimising PUE, reducing water and energy use, and building fuel flexibility. These measures directly insulate facilities from energy shocks, while ecosystem initiatives alone do not.
To build this capability, skilled teams and disciplined processes are essential. The Uptime Institute’s 2014 Operational Sustainability framework provides the proven blueprint.